Models · GLM
 GLM-4.7-Flash
A smaller long-context cache for GLM.
GLM-4.7 keeps a compact latent attention cache, like DeepSeek's. weights.zip is extending its DeepSeek cache work to GLM serving, so each GPU can hold more context for more users. Early access is open now.
For labs and inference providers serving GLM
Early access
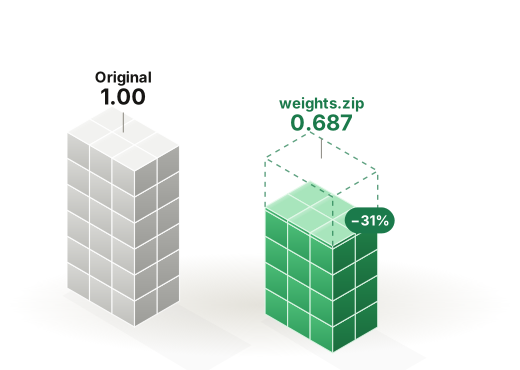
What it is built to deliver
- Less cache memory per token than today's 8-bit formats.
- More concurrent long-context users on every GPU.
- No retraining and no changes to the model weights.
Good fit when
- You serve GLM-4.7 or plan to.
- Cache memory limits users per GPU at long context.
- You want to test on your own traffic before results are published.
Live benchmarks are under way.
We publish a model's numbers only once they have been measured on live model output and re-checked by an independent verifier, as on our DeepSeek, Nemotron and Llama pages. GLM results will appear here when that is complete. Early-access partners get them first, measured on their own prompts.
Request early accessFree benchmark on your models and traffic.
- Tell us your stackThe models you serve, your context lengths and your serving engine.
- Get your numbersMemory saved, quality against your current format and capacity per GPU, measured on your prompts.
- PilotRun on one workload for 30 days. Pricing is a share of the measured saving.
Built for the models you serve.
Model names and logos are trademarks of their owners and are used only to identify the models tested. weights.zip is not affiliated with or endorsed by DeepSeek, NVIDIA, Z.ai, Meta or MiniMax.