 Llama-3.1 8B and 70B
Up to 2.7× the long-context Llama users on every GPU.
The most complete results in the weights.zip line. Keep Llama's KV cache bit for bit exact at 1.6× the capacity, or choose 4-bit, 3.5-bit or 3-bit formats that serve 2.2 to 2.7× as many 128k-context users per GPU as fp8. Measured on NVIDIA H100 and H200.
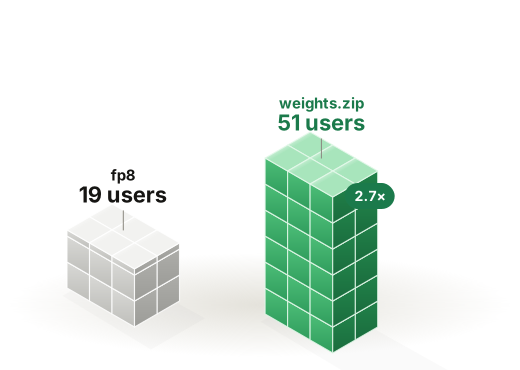
More users on every card, at every precision.
Concurrent 128k-token sessions that fit after the model weights and activations. Bars are drawn to scale.
Llama-3.1-8B on one 80 GB H100
Llama-3.1-70B on one 8x H100 node
The KV budget is 92% of GPU memory less the bf16 weights and 4 GB of activations per GPU: 58.6 GB for the 8B on one H100, 416 GB for the 70B on an 8x H100 node.
| Format | Capacity vs fp8 | Output | Best for |
|---|---|---|---|
| Lossless | 1.6× vs bf16 | identical, bit for bit | cache tiers where answers must not change |
| 4-bit | 2.2× | about half of int4's error on the 8B, level with int4 on the 70B | quality-first long-context serving |
| 3.5-bit | 2.5× | int4-level text quality and retrieval on the 8B | providers already running int4-class caches |
| 3-bit | 2.7× | int4-level retrieval on the 8B | agents, document retrieval, code assistants |
Capacity for the 8B on one H100. Full details are on the KV Cache, FP8 and 3-bit pages.
Measured on Llama-3.1 8B and 70B, out to 128k tokens.
Lossless cache · NVIDIA H200, every tensor identical| Model | Capacity gain | Restore 128k from CPU memory | Recompute the prompt |
|---|---|---|---|
| Llama-3.1-8B | 1.58× | 0.31 s | 18.8 s |
| Llama-3.1-70B | 1.59× | 0.74 s | 248.6 s |
Measured at 8k, 32k and 128k tokens, with every restored tensor checked against the original. Recompute is a full prefill with Hugging Face Transformers on the same H200.
Decode attention speed vs fp8 · NVIDIA H100, batch 8 to 64| Format | Llama-3.1-8B | Llama-3.1-70B, 128k |
|---|---|---|
| weights.zip 4-bit | 1.31 to 1.54× | 1.38 to 1.55× |
| weights.zip 3.5-bit | 1.57 to 1.89× | 1.62 to 1.84× |
Against NVIDIA's TensorRT-LLM XQA kernel for fp8. On the 8B, the 3.5-bit format matches a fully tuned int4 kernel on decode speed. On multi-key retrieval it sits slightly below int4, within measurement noise.
Quality and retrieval at 128k| Measure | int4 | weights.zip |
|---|---|---|
| 8B error, 4-bit | 1× | 0.55× |
| 8B words changed, 4-bit | 8.6% | 6.3% |
| 8B multi-key retrieval, 64k to 128k pooled, 3.5-bit (H100) | 90.9% | 89.4% |
| 8B multi-key retrieval at 128k, 3.5-bit (H100) | 81.8% | 77.3% |
| 70B error on held-out text, 4-bit | 1× | 0.91 to 0.97× |
Error is average KL divergence of next-token predictions against the uncompressed bf16 model, scored at every position of held-out 131,072-token windows. Retrieval results were independently re-analysed from the raw outputs.
Plugs into vLLM. No retraining.
- Lossless tierA vLLM KV connector stores and restores cached context, so returning requests skip the prefill.
- Compact formatsA one-time offline step per model, then drop-in decode attention and cache-write kernels for a paged cache.
- Pilot on your trafficWe measure capacity, speed and quality on your Llama models and prompts.
Free benchmark on your models and traffic.
- Tell us your stackThe models you serve, your context lengths and your serving engine.
- Get your numbersMemory saved, quality against your current format and capacity per GPU, measured on your prompts.
- PilotRun on one workload for 30 days. Pricing is a share of the measured saving.
Built for the models you serve.
Model names and logos are trademarks of their owners and are used only to identify the models tested. weights.zip is not affiliated with or endorsed by DeepSeek, NVIDIA, Z.ai, Meta or MiniMax.